Chromatography software saves runs in proprietary formats that R
can’t read directly. read_chroms() reads them into a
chrom_list, a list of chromatograms that keep the file’s
metadata with them. This vignette shows how to read a sequence of
standards from ChemStation, use the metadata to view and select runs,
and fit a calibration curve to the peak tables.
> library(chromConverter)Reading a sequence
The example is a calibration series of benzoxazinoid standards, run on an Agilent 1100 series diode array detector: nine dilutions of a mixed standard of DIBOA, DIMBOA, BOA and MBOA ranging from 1000 to 4 ppm, and a methanol blank run with the same method five days earlier.
> seq_dir <- system.file("extdata", "benzoxazinoid_standards",
+                        package = "chromConverter")
> list.files(seq_dir)
 [1] "BENZOS_1000PPM.D"  "BENZOS_125PPM.D"   "BENZOS_16PPM.D"
 [4] "BENZOS_250PPM.D"   "BENZOS_31,25PPM.D" "BENZOS_4PPM.D"
 [7] "BENZOS_500PPM.D"   "BENZOS_62,5PPM.D"  "BENZOS_8PPM.D"
[10] "MEOH.D"
read_chroms() searches the directory for files in the
format given by format_in. Each .D holds a
trace per wavelength, and pattern picks out
dad1A, the 254 nm trace, from every run.
> chroms <- read_chroms(seq_dir, format_in = "chemstation_ch",
+                       pattern = "dad1A", parser = "chromconverter",
+                       progress_bar = FALSE)
Files found in a directory come back in the order they were injected,
not alphabetically; sort_by changes this.
parser = "chromconverter" picks chromConverter’s own
reader, which extracts the wavelength as a metadata field.
Viewing sequence metadata
Printing a chrom_list shows its metadata rather than its
data, since even this short sequence holds ten traces each containing
9000 rows of data. To see the raw data, pull out a single chromatogram
(see Working with a single
chromatogram).
> chroms
A chrom_list with 10 chromatograms
method: ETHAN_DT_MEOH_L16-6.M  |  detector: DAD  |  wavelength: 254
              name     sample_name        run_datetime
1             MEOH            MEOH 2023-06-15 16:46:23
2   BENZOS_1000PPM  benzos_1000ppm 2023-06-20 19:29:41
3    BENZOS_500PPM   benzos_500ppm 2023-06-21 15:23:43
4    BENZOS_250PPM   benzos_250ppm 2023-06-21 16:46:40
5    BENZOS_125PPM   benzos_125ppm 2023-06-21 18:02:48
6   BENZOS_62,5PPM  benzos_62,5ppm 2023-06-21 19:19:00
7  BENZOS_31,25PPM benzos_31,25ppm 2023-06-21 20:35:12
8     BENZOS_16PPM    benzos_16ppm 2023-06-21 21:51:21
9      BENZOS_8PPM     benzos_8ppm 2023-06-21 23:07:28
10     BENZOS_4PPM     benzos_4ppm 2023-06-22 00:23:39
Fields that are the same for every run, here the method, detector and wavelength, are collapsed into the header, and the fields that differ between samples are printed in a table with a column for each field.
summary() puts the same fields in a data frame with one
row per chromatogram, and also adds the number of rows and columns in
each chromatogram. Its cols argument picks the fields:
> summary(chroms, cols = c("run_datetime", "wavelength"))
            sample n_rows n_cols        run_datetime wavelength
1             MEOH   9000      1 2023-06-15 16:46:23        254
2   BENZOS_1000PPM   9001      1 2023-06-20 19:29:41        254
3    BENZOS_500PPM   9001      1 2023-06-21 15:23:43        254
4    BENZOS_250PPM   9000      1 2023-06-21 16:46:40        254
5    BENZOS_125PPM   9001      1 2023-06-21 18:02:48        254
6   BENZOS_62,5PPM   9001      1 2023-06-21 19:19:00        254
7  BENZOS_31,25PPM   9000      1 2023-06-21 20:35:12        254
8     BENZOS_16PPM   9001      1 2023-06-21 21:51:21        254
9      BENZOS_8PPM   9001      1 2023-06-21 23:07:28        254
10     BENZOS_4PPM   9001      1 2023-06-22 00:23:39        254
extract_metadata() returns any field as a column,
including ones that summary() leaves out, such as each
run’s time range.
> extract_metadata(chroms, "time_range")
              name time_range1 time_range2
1             MEOH -0.03716667    59.95617
2   BENZOS_1000PPM -0.04333333    59.95667
3    BENZOS_500PPM -0.04233333    59.95767
4    BENZOS_250PPM -0.03783333    59.95550
5    BENZOS_125PPM -0.04166667    59.95833
6   BENZOS_62,5PPM -0.04016667    59.95983
7  BENZOS_31,25PPM -0.03716667    59.95617
8     BENZOS_16PPM -0.03933333    59.96067
9      BENZOS_8PPM -0.04050000    59.95950
10     BENZOS_4PPM -0.03933333    59.96067
Without what, extract_metadata() returns
all the standard fields. To keep the vendor’s own field names instead,
pass metadata_format = "raw" to
read_chroms.
Selecting and annotating chromatograms
subset() keeps the chromatograms whose metadata match a
condition, using the field names that summary() and
extract_metadata() report. To set the blank aside:
> subset(chroms, sample_name != "MEOH")
A chrom_list with 9 chromatograms
method: ETHAN_DT_MEOH_L16-6.M  |  detector: DAD  |  wavelength: 254
             name     sample_name        run_datetime
1  BENZOS_1000PPM  benzos_1000ppm 2023-06-20 19:29:41
2   BENZOS_500PPM   benzos_500ppm 2023-06-21 15:23:43
3   BENZOS_250PPM   benzos_250ppm 2023-06-21 16:46:40
4   BENZOS_125PPM   benzos_125ppm 2023-06-21 18:02:48
5  BENZOS_62,5PPM  benzos_62,5ppm 2023-06-21 19:19:00
6 BENZOS_31,25PPM benzos_31,25ppm 2023-06-21 20:35:12
7    BENZOS_16PPM    benzos_16ppm 2023-06-21 21:51:21
8     BENZOS_8PPM     benzos_8ppm 2023-06-21 23:07:28
9     BENZOS_4PPM     benzos_4ppm 2023-06-22 00:23:39
Indexing with [ also returns a chrom_list,
and c() combines them.
> c(chroms["MEOH"], chroms["BENZOS_4PPM"])
A chrom_list with 2 chromatograms
method: ETHAN_DT_MEOH_L16-6.M  |  detector: DAD  |  wavelength: 254
         name sample_name        run_datetime
1        MEOH        MEOH 2023-06-15 16:46:23
2 BENZOS_4PPM benzos_4ppm 2023-06-22 00:23:39
add_metadata() attaches the columns of your own table as
new fields, matching its rows to the samples by name, so
subset() and extract_metadata() can use them.
chromatographR’s get_peaktable() carries them into its peak
table.
> sheet <- data.frame(name = c("MEOH", "BENZOS_1000PPM", "BENZOS_500PPM",
+                              "BENZOS_250PPM", "BENZOS_125PPM",
+                              "BENZOS_62,5PPM", "BENZOS_31,25PPM",
+                              "BENZOS_16PPM", "BENZOS_8PPM", "BENZOS_4PPM"),
+                     ppm = c(0, 1000, 500, 250, 125, 62.5, 31.25, 15.625,
+                             7.8125, 3.90625))
> annotated <- add_metadata(chroms, sheet)
> subset(annotated, ppm < 20)
A chrom_list with 4 chromatograms
method: ETHAN_DT_MEOH_L16-6.M  |  detector: DAD  |  wavelength: 254
          name  sample_name        run_datetime
1         MEOH         MEOH 2023-06-15 16:46:23
2 BENZOS_16PPM benzos_16ppm 2023-06-21 21:51:21
3  BENZOS_8PPM  benzos_8ppm 2023-06-21 23:07:28
4  BENZOS_4PPM  benzos_4ppm 2023-06-22 00:23:39
The blank is kept as well, since its concentration is 0.
Working with a single chromatogram
Where [ returns a smaller chrom_list,
$ or [[ pulls out a single chromatogram.
> x <- chroms$BENZOS_4PPM
> head(x)
                       intensity
-0.0393333333333333 -0.012874603
-0.0326666666666667 -0.001907349
-0.026               0.015735626
-0.0193333333333333  0.072956085
-0.0126666666666667  0.204563141
-0.006               0.409126282
By default, a single-wavelength trace is returned as a matrix with
retention times as row names and one column of intensities; DAD data
have a column per wavelength. The format_out and
data_format arguments in read_chroms() can be
used to return a data.frame or data.table, or
long rather than wide data.
A chromatogram keeps its metadata as attributes, even outside the
chrom_list:
> attr(x, "run_datetime")
[1] "2023-06-22 00:23:39 UTC"
> attr(x, "detector_model")
[1] "G1315A"Working with nested samples
So far each sample has held a single chromatogram. However, the
.D directory holds several data types that can all be
extracted with read_chroms. The what argument
can be used to specify which data to extract. Here it is used to request
three data types: the chromatographic traces at all five wavelengths
(chroms), the peak report containing ChemStation
integration results (peak_table), and the pump’s record of
pressure, flow and solvent composition (instrument).
> run <- read_chroms(file.path(seq_dir, "BENZOS_250PPM.D"),
+                    format_in = "agilent_d",
+                    what = c("chroms", "peak_table", "instrument"),
+                    progress_bar = FALSE)
> print(run, cols = "wavelength")
A chrom_list with 1 sample (16 chromatograms)
BENZOS_250PPM
               name wavelength
  1    chroms.dad1A        254
  2    chroms.dad1B        230
  3    chroms.dad1C        320
  4    chroms.dad1D        360
  5    chroms.dad1E        210
  6  peak_table.254        254
  7  peak_table.320        320
  8  peak_table.360        360
  9  peak_table.210        210
  10 peak_table.230        230
... with 6 more chromatograms
All 16 elements are listed under their one sample,
BENZOS_250PPM. summary() gives each a row,
with a trace column holding its path within the sample,
such as chroms.dad1A, peak_table.254 or
instrument.PMP1, Pressure.
> summary(run)[c("sample", "trace", "wavelength")]
          sample                      trace wavelength
1  BENZOS_250PPM               chroms.dad1A        254
2  BENZOS_250PPM               chroms.dad1B        230
3  BENZOS_250PPM               chroms.dad1C        320
4  BENZOS_250PPM               chroms.dad1D        360
5  BENZOS_250PPM               chroms.dad1E        210
6  BENZOS_250PPM             peak_table.254        254
7  BENZOS_250PPM             peak_table.320        320
8  BENZOS_250PPM             peak_table.360        360
9  BENZOS_250PPM             peak_table.210        210
10 BENZOS_250PPM             peak_table.230        230
11 BENZOS_250PPM  instrument.PMP1, Pressure         NA
12 BENZOS_250PPM      instrument.PMP1, Flow         NA
13 BENZOS_250PPM instrument.PMP1, Solvent A         NA
14 BENZOS_250PPM instrument.PMP1, Solvent B         NA
15 BENZOS_250PPM instrument.PMP1, Solvent C         NA
16 BENZOS_250PPM instrument.PMP1, Solvent D         NA
subset() keeps or drops a nested sample as a whole (see
?subset.chrom_list), so it can’t pick out traces within
one. Index the nested lists with $ or [[
instead. Each peak table is named by the wavelength of its signal and
has the columns rt, start, end,
area, height and FWHM (full width
at half maximum). ChemStation reports don’t record where peaks start and
end, so those columns are NA here.
> peaks <- run$BENZOS_250PPM$peak_table[["254"]]
> head(peaks)
     rt start end      area   height   FWHM
1 1.948    NA  NA  140.9592  7.07890 0.2483
2 2.373    NA  NA  161.7452 14.59622 0.1433
3 2.517    NA  NA  108.1190 16.77651 0.0912
4 2.669    NA  NA  102.5438 21.65732 0.0752
5 2.769    NA  NA  389.2521 31.26716 0.1612
6 3.898    NA  NA 1211.7677 18.42384 0.7973
ChemStation also integrated the disturbance at the solvent front and baseline noise as peaks; only the four standards stand out from it: DIBOA, DIMBOA, BOA and MBOA, in order of elution.
> real <- subset(peaks, rt > 10 & height > 5)
> trace <- run$BENZOS_250PPM$chroms$dad1A
> plot(as.numeric(rownames(trace)), trace[, 1], type = "l", ylim = c(-20, 500),
+      xlab = "Time (min)", ylab = "Absorbance (mAU)")
> text(real$rt, real$height, c("DIBOA", "DIMBOA", "BOA", "MBOA"),
+      adj = c(0, -0.5), cex = 0.8)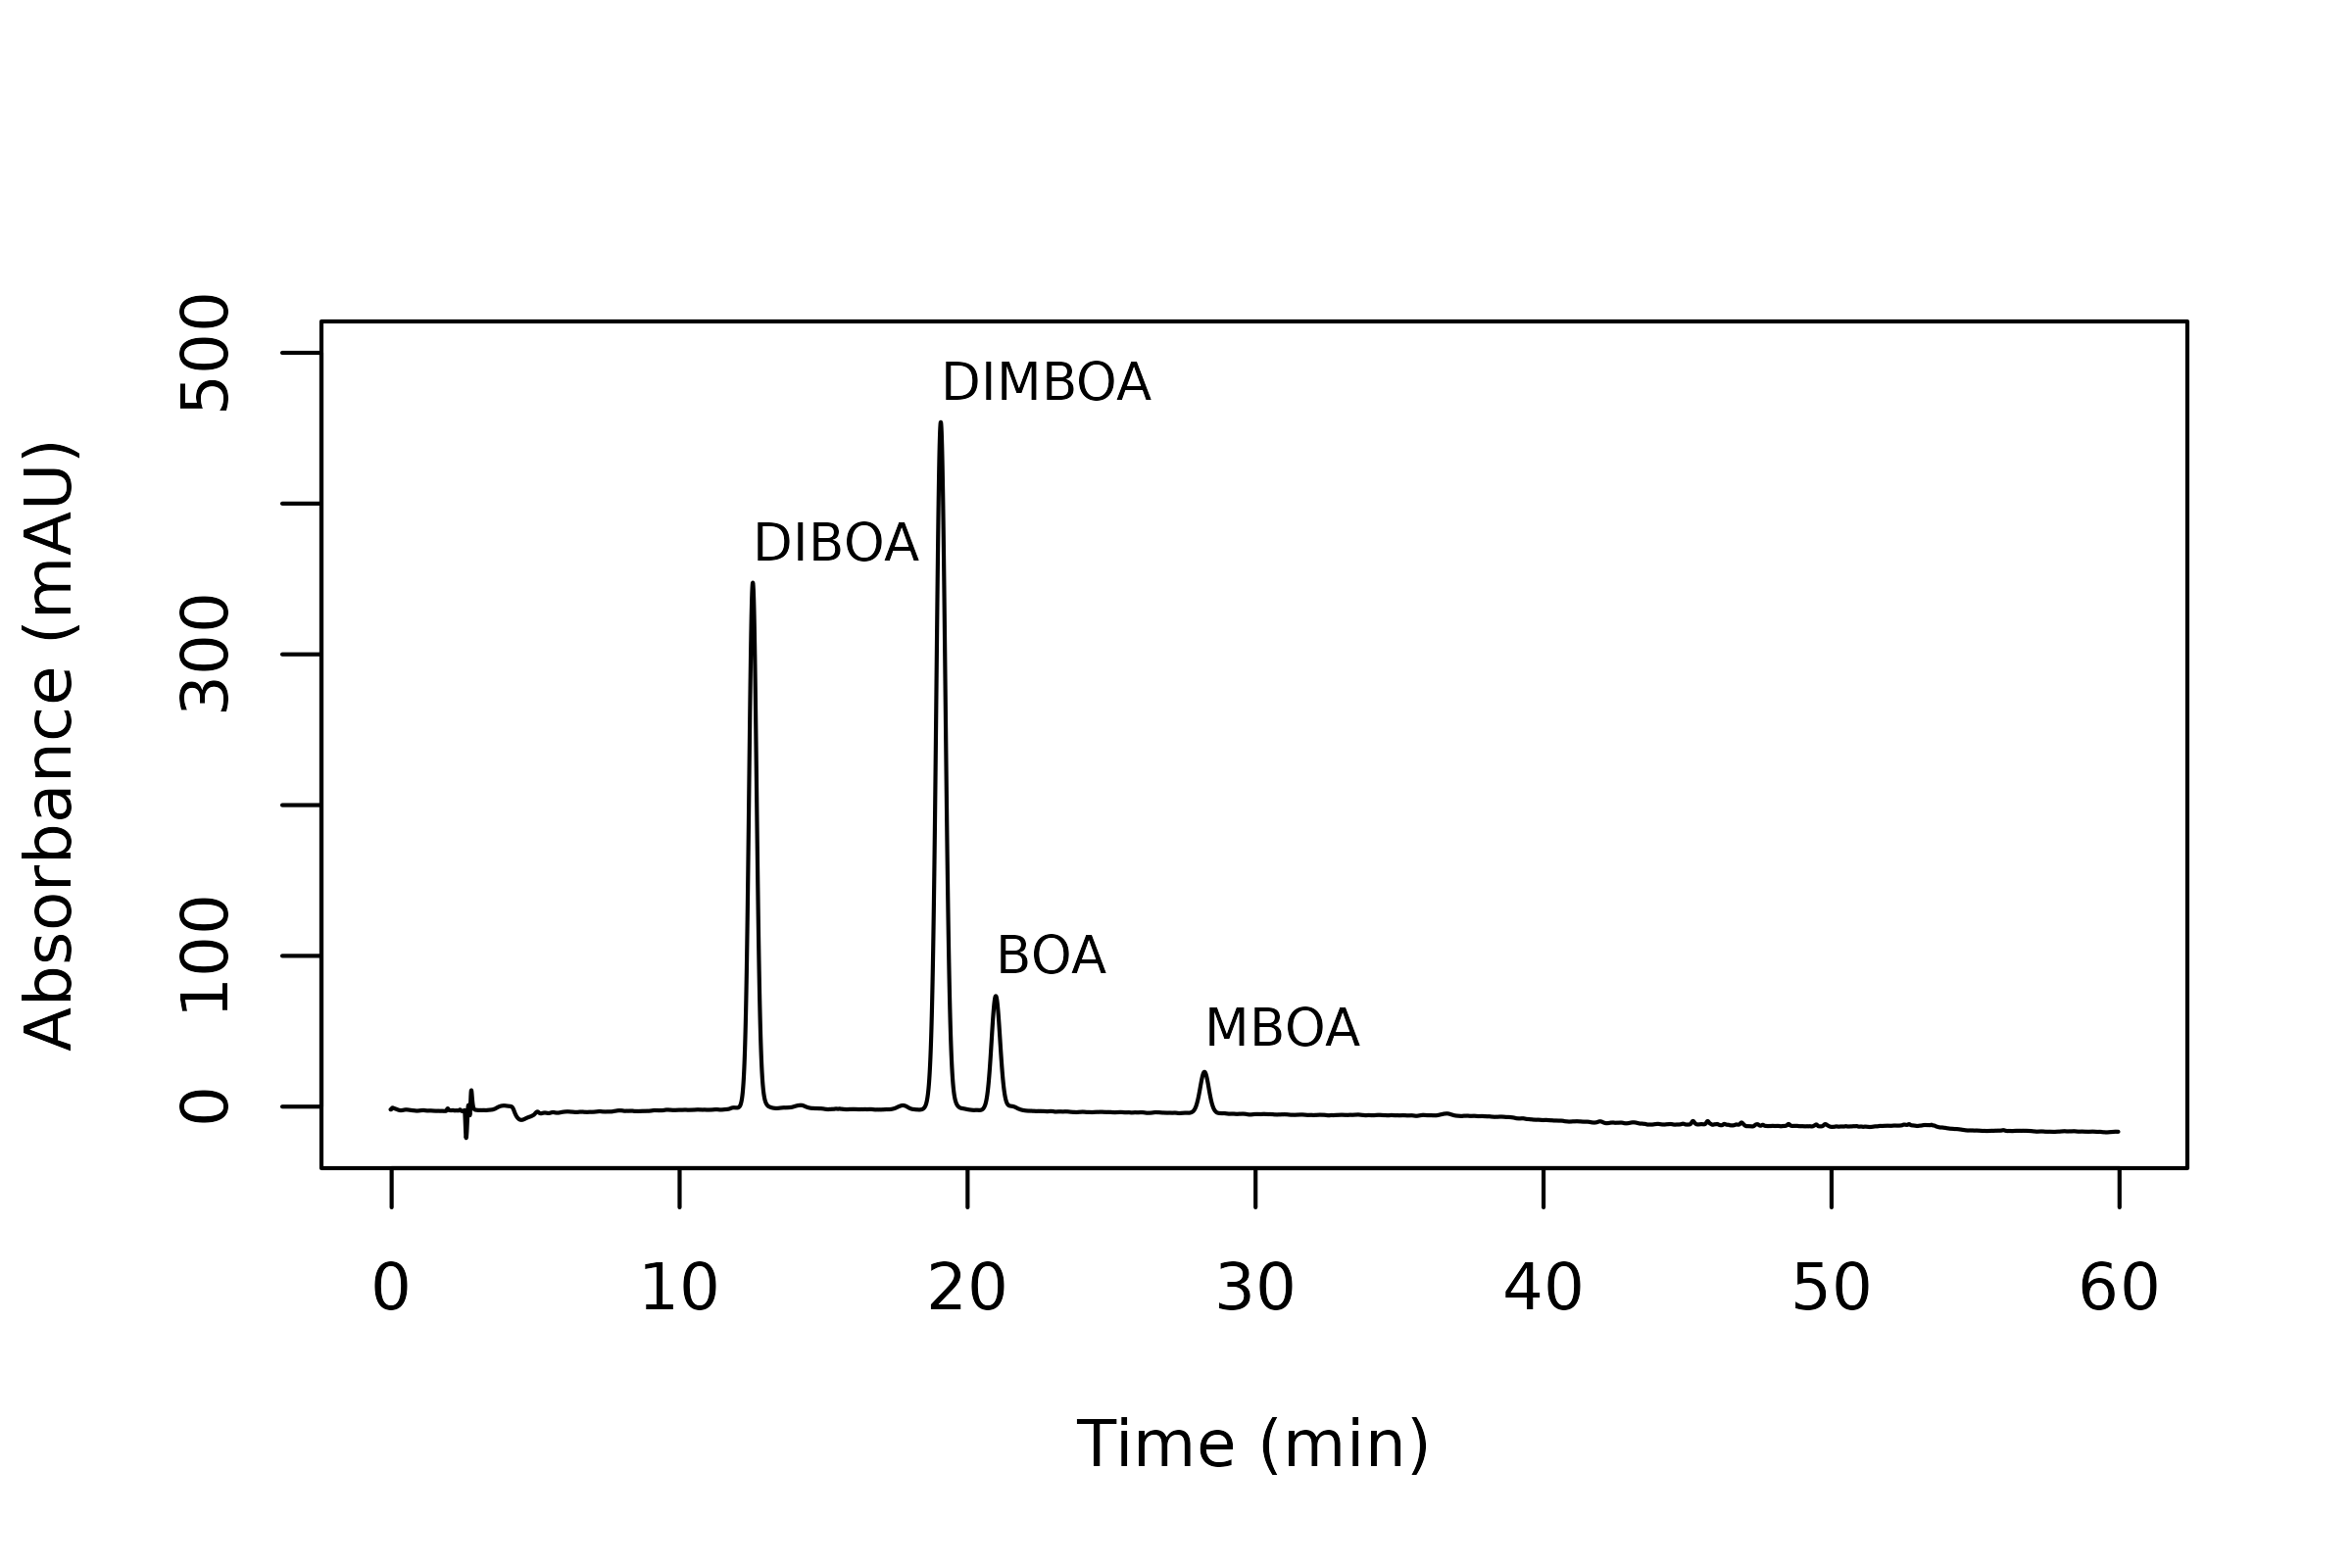
The instrument list holds one trace per quantity the
pump recorded, under the names given by ChemStation. Plotting the
pressure under the chromatogram puts both on the same time axis, so a
disturbance in one can be matched to the other.
> names(run$BENZOS_250PPM$instrument)
[1] "PMP1, Pressure"  "PMP1, Flow"      "PMP1, Solvent A" "PMP1, Solvent B"
[5] "PMP1, Solvent C" "PMP1, Solvent D"
> pressure <- run$BENZOS_250PPM$instrument[["PMP1, Pressure"]]
> op <- par(mfrow = c(2, 1), mar = c(0.5, 4, 1, 1), oma = c(4, 0, 0, 0))
> plot(as.numeric(rownames(trace)), trace[, 1], type = "l", xaxt = "n",
+ xlab = "", ylab = "Absorbance (mAU)")
> par(mar = c(0, 4, 0.5, 1))
> plot(as.numeric(rownames(pressure)), pressure[, 1], type = "l",
+ xlab = "", ylab = "Pressure (bar)")
> mtext("Time (min)", side = 1, line = 2.5, outer = TRUE)
> par(op)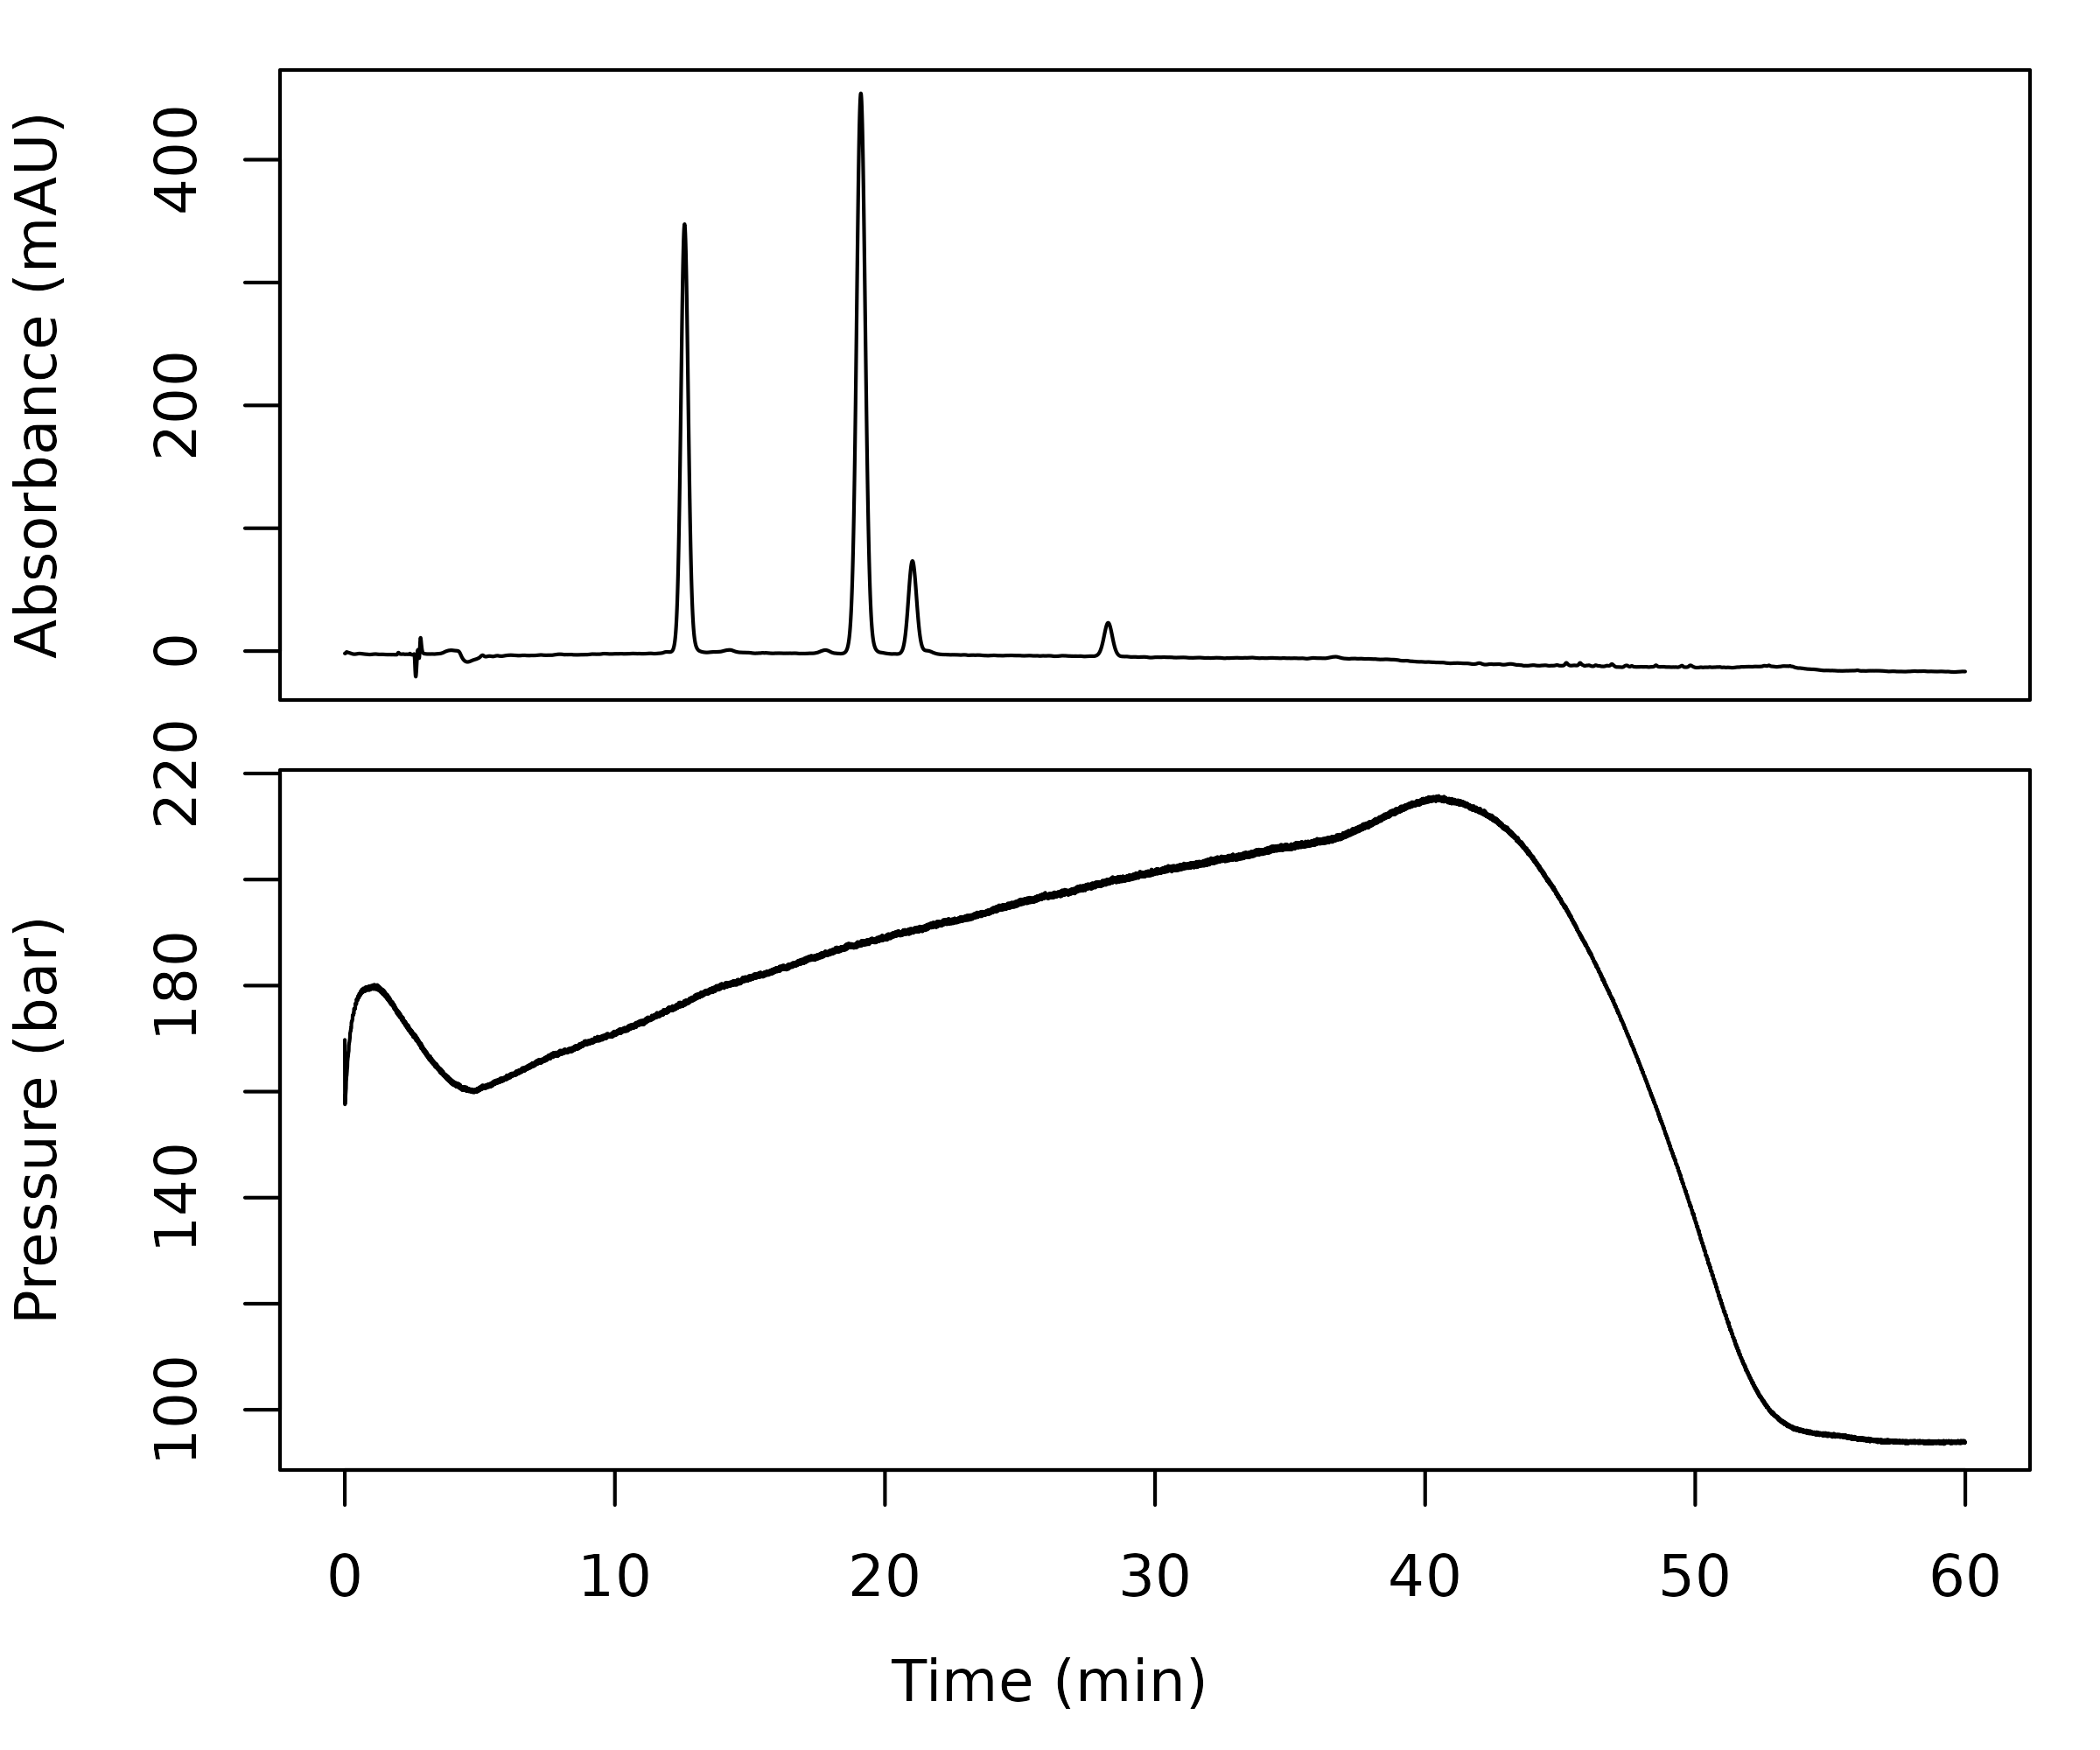
Reading peak tables from a sequence
read_chroms() can return peak tables along with the
traces, as above. Alternatively, read_peaklist() reads only
the peak tables, labelling each by sample and wavelength so that tables
from different runs stack directly:
> peak_list <- read_peaklist(seq_dir, format_in = "chemstation",
+                            progress_bar = FALSE)
> names(peak_list$BENZOS_250PPM)
[1] "254" "320" "360" "210" "230"
Combining the 254 nm tables gives one data frame for the whole sequence. DIMBOA is the only peak between 18.5 and 20.3 minutes in every run, so you can select it by retention time, then merge in the concentrations from earlier:
> at254 <- do.call(rbind, lapply(peak_list, `[[`, "254"))
> dimboa <- subset(at254, rt > 18.5 & rt < 20.3)
> dimboa <- merge(dimboa, extract_metadata(annotated, "ppm"),
+                 by.x = "sample", by.y = "name")
> dimboa[c("sample", "rt", "area", "ppm")]
           sample     rt       area        ppm
1  BENZOS_1000PPM 19.192 39478.0000 1000.00000
2   BENZOS_125PPM 19.262  5362.0581  125.00000
3    BENZOS_16PPM 19.799   758.5371   15.62500
4   BENZOS_250PPM 19.068 10954.2000  250.00000
5 BENZOS_31,25PPM 19.703  1423.1617   31.25000
6     BENZOS_4PPM 19.713   216.2569    3.90625
7   BENZOS_500PPM 19.341 20482.1000  500.00000
8  BENZOS_62,5PPM 19.515  2975.4404   62.50000
9     BENZOS_8PPM 19.804   365.0165    7.81250
Each standard now has one row, holding its DIMBOA peak area and concentration. A linear fit of area against concentration gives the calibration curve:
> fit <- lm(area ~ ppm, data = dimboa)
> plot(area ~ ppm, data = dimboa, xlab = "DIMBOA (ppm)",
+      ylab = "Peak area (mAU s)", pch = 20)
> abline(fit, col = "gray20")
> legend("topleft", sprintf("R² = %.4f", summary(fit)$r.squared), bty = "n")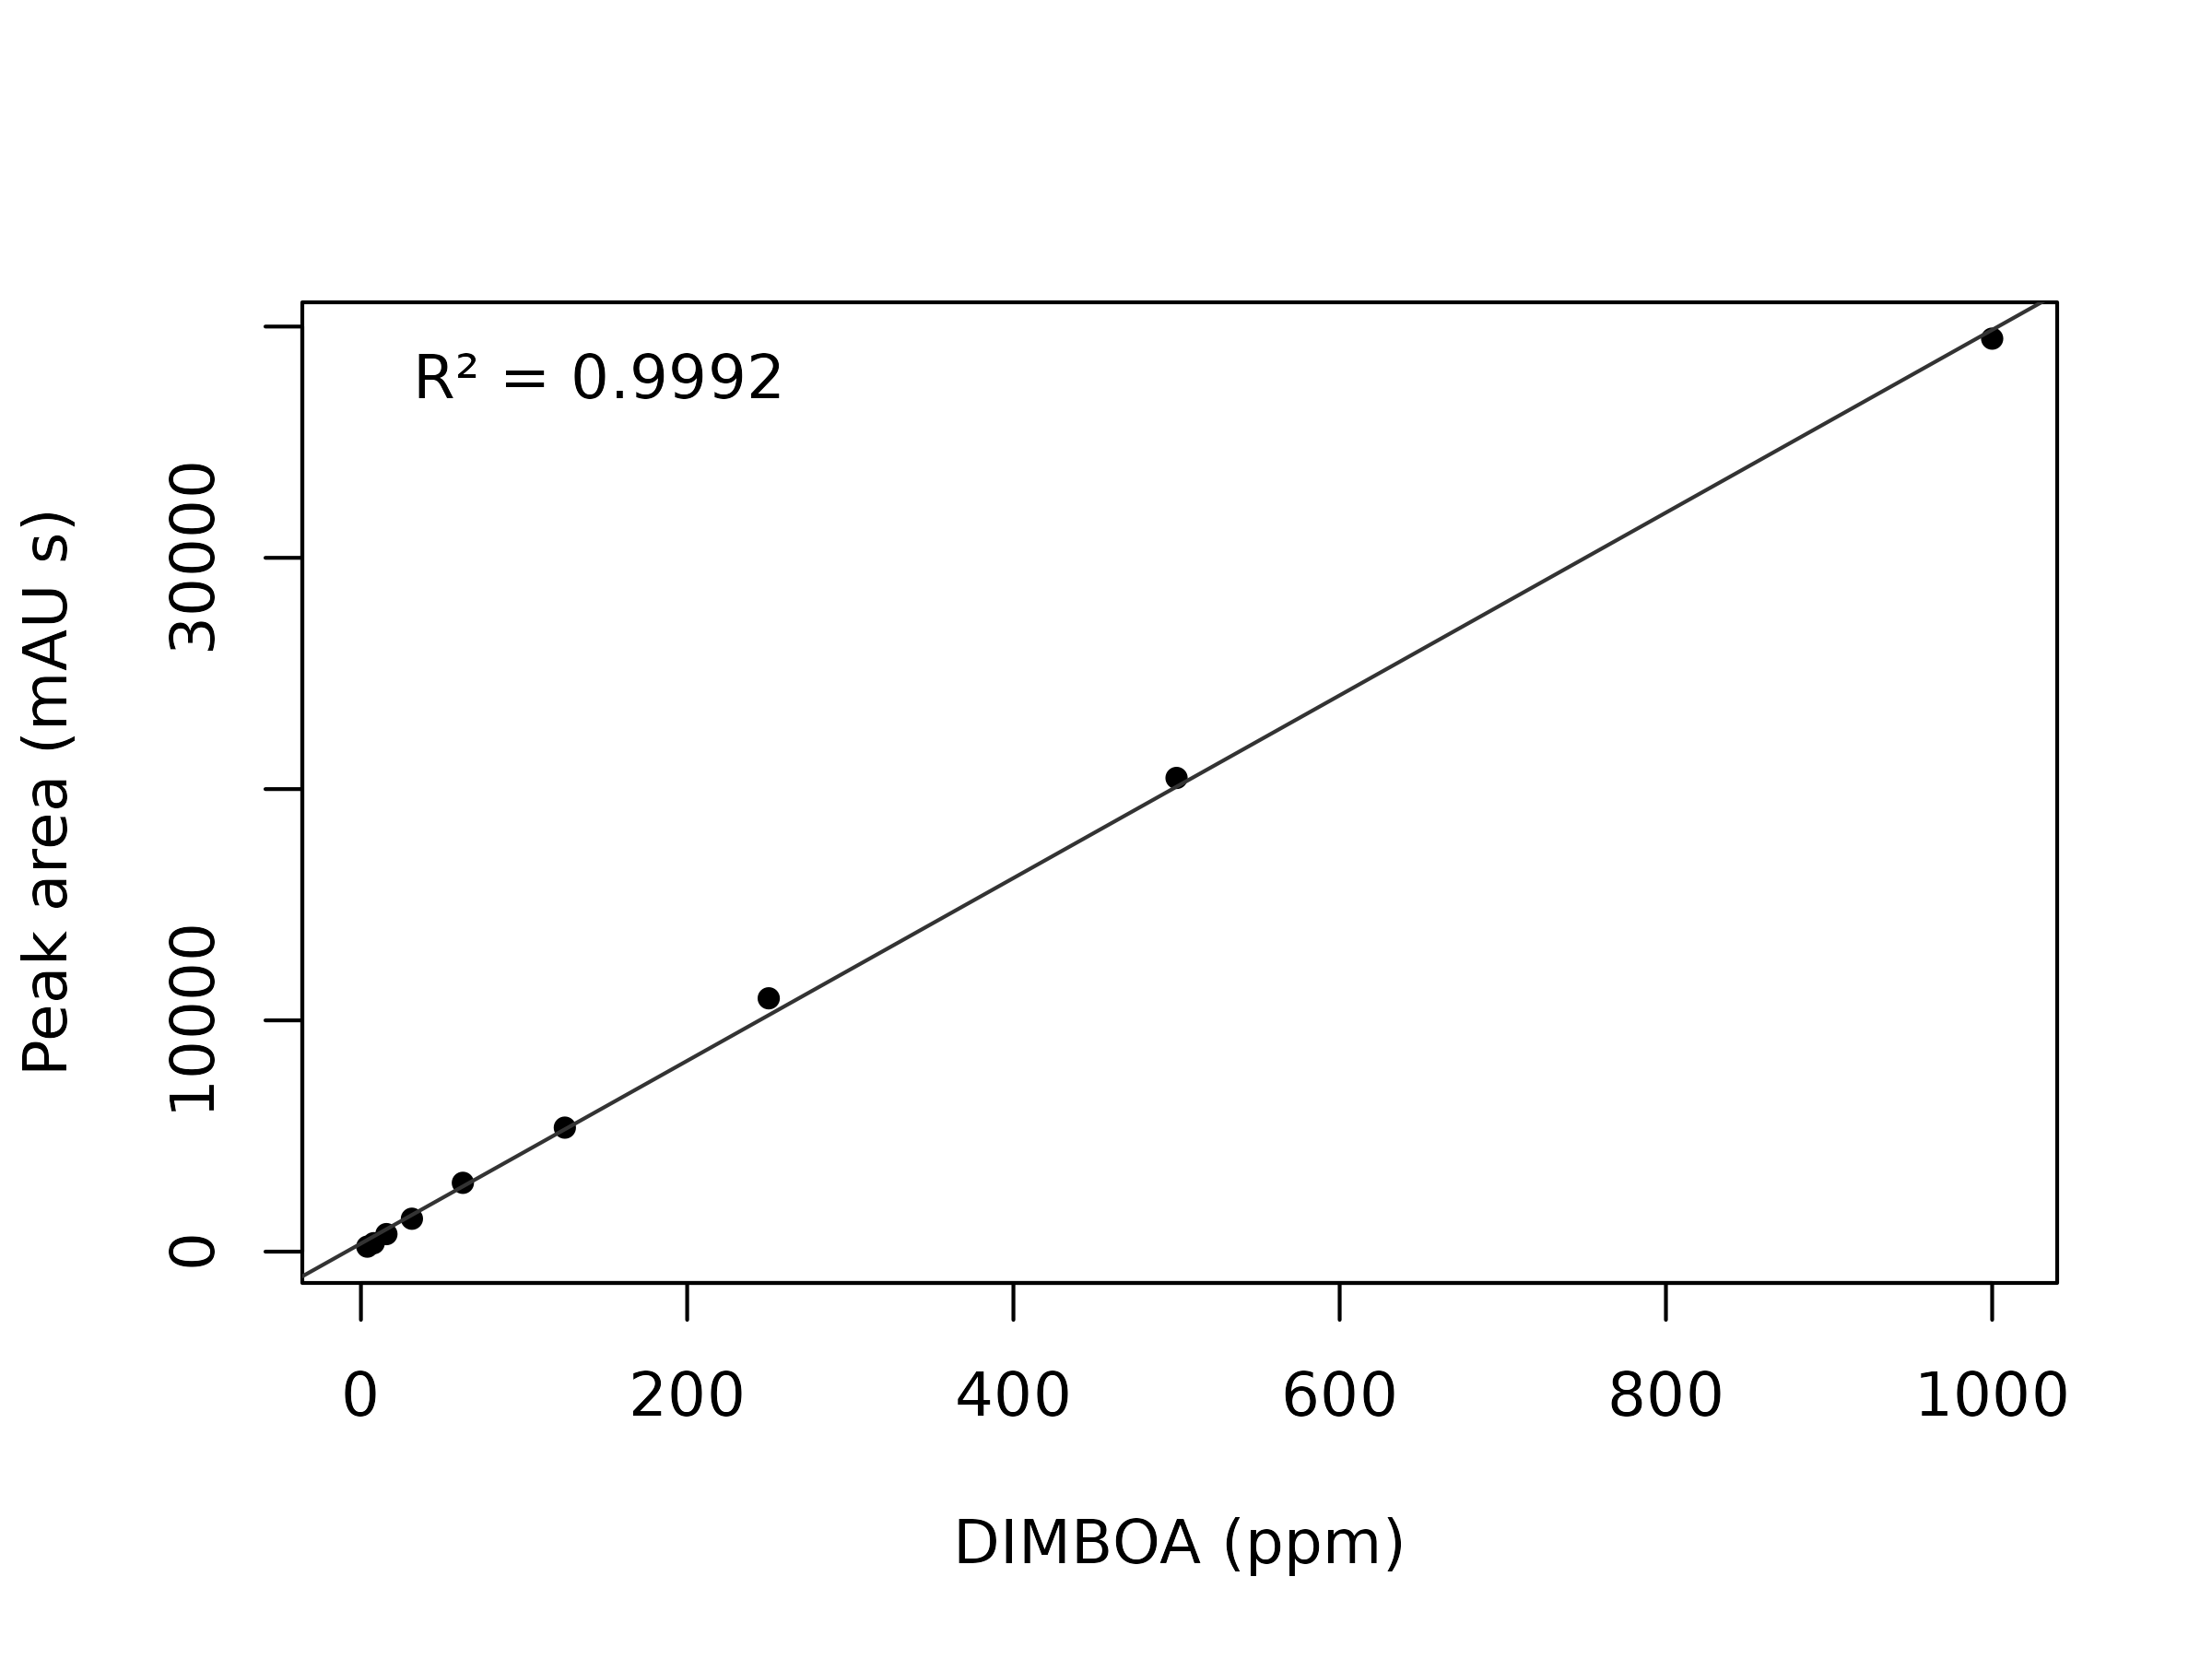
See also
- chromatographR aligns, integrates and compares chromatograms read with chromConverter.
- Plotting mass spectrometry data covers the long-format data returned for MS files.